More tasks, lower cost: Midpoint on g-harness-evals
Midpoint’s pre-release g-harness-evals run reached 90.0% on GPT-6.1 Sol and 83.8% on Claude Opus 5.5. Results, costs and limits.

A 90.0% pass rate. $0.13 per solved task.
That’s Midpoint running GPT-6.1 Sol in our November 9 test of a pre-release build on Garry Tan’s g-harness-evals, which compares how well different AI agent harnesses complete workplace tasks.
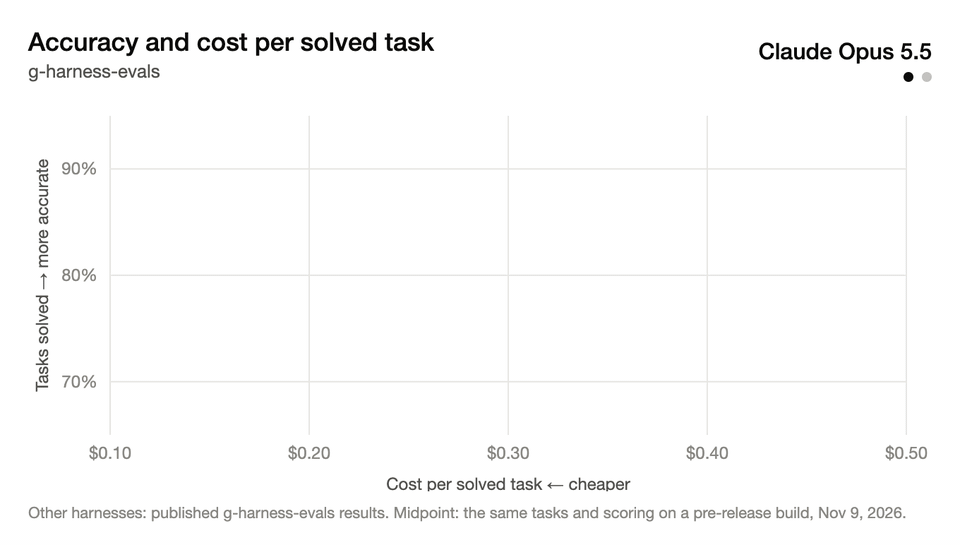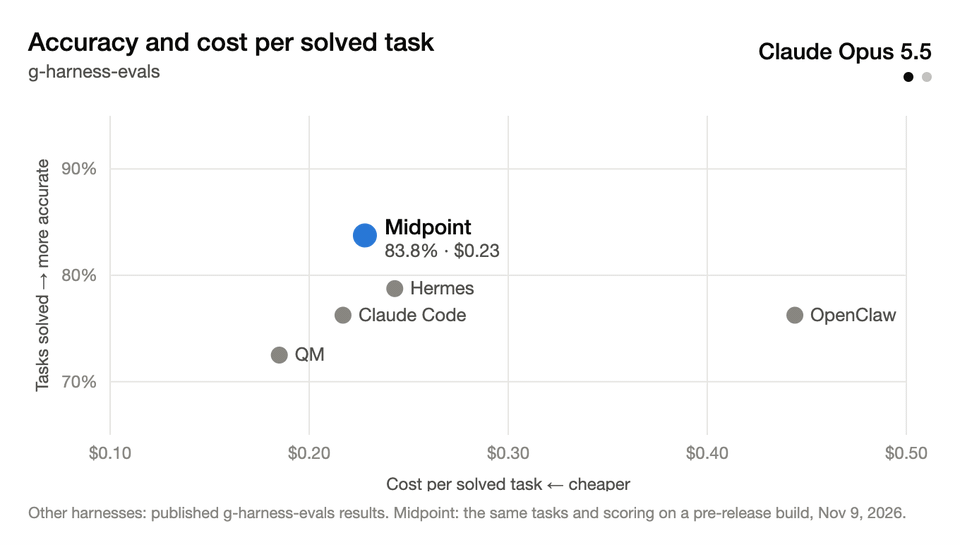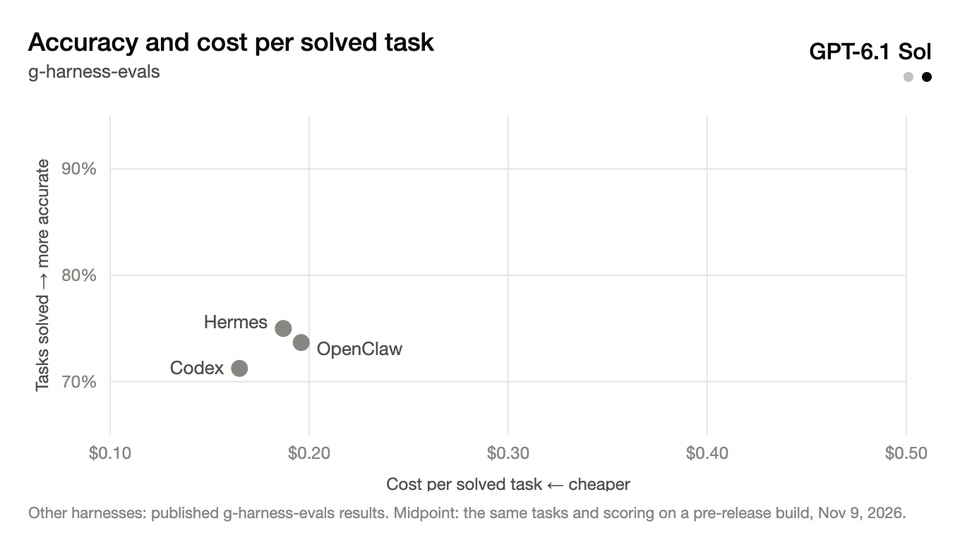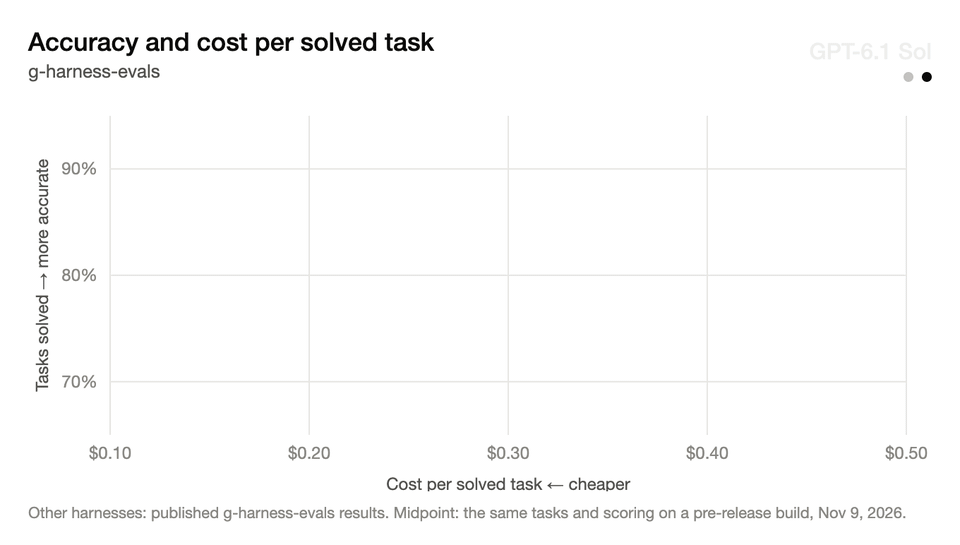
Published g-harness-evals results alongside Midpoint’s own pre-release run, November 9, 2026. Higher is a better pass rate; further left is a lower cost per solved task.
With the same model, the published results range from 71.3% to 75.0%, at $0.17–$0.22 per solved task. Our run completed more tasks at a lower cost per success.
On Claude Opus 5.5, Midpoint reached 83.8% at $0.23 per solved task: a higher observed pass rate than the published Opus results, at a cost close to Claude Code and Hermes Agent.
More finished work for the same budget. That’s the direction we’re pushing Midpoint.